
Muslim
- Software Development
- October 12, 2026
- 66 views
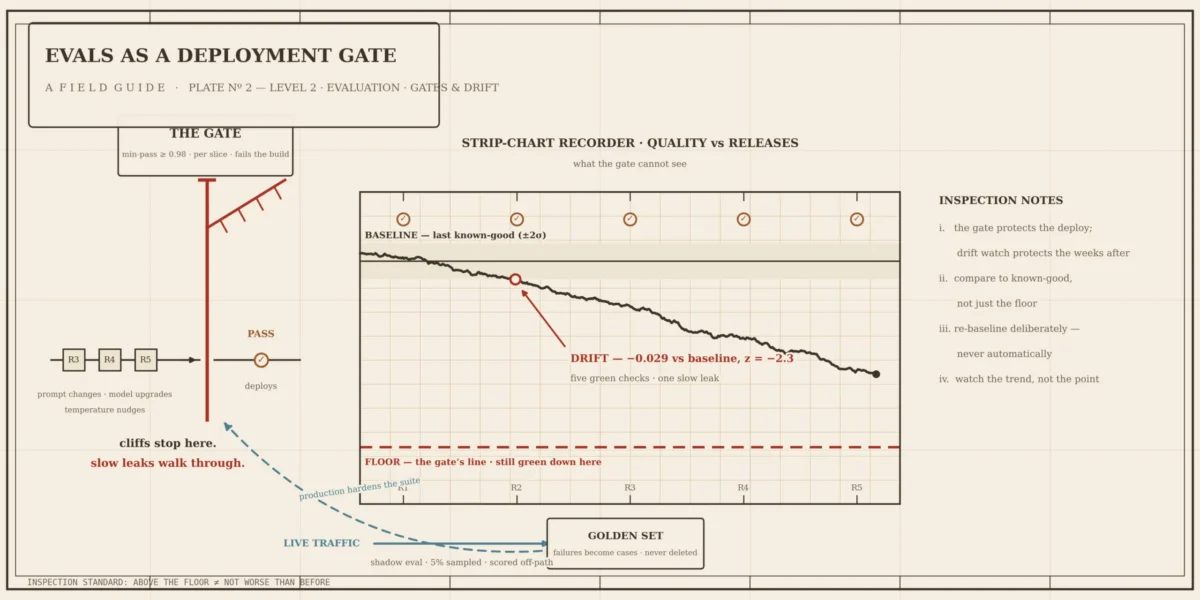
Beyond the Notebook: Engineering Robust Evaluation Systems for LLM Production
In the burgeoning field of Large Language Model (LLM) operations, a dangerous misconception persists: that testing a prompt change in a Jupyter notebook constitutes an "evaluation strategy." For many engineering…
Azzam Bilal Chamdy
- Software Development
- October 10, 2026
- 25 views
Beyond the Hype: Introducing ReviewBench, the New Gold Standard for AI Code Review Evaluation
As agentic AI shifts from a experimental novelty to a cornerstone of modern software engineering, the ability to automate code review has become a competitive necessity. AI-driven reviewers are now…
Ammar Sabilarrohman
- E-commerce and Retail
- May 17, 2026
- 74 views
Amazon Overhauls Customer Service Metrics: A Strategic Shift in Seller Performance Evaluation
Amazon has officially announced a significant structural change to the way it evaluates third-party seller performance, specifically regarding customer service satisfaction. Effective April 17, 2026, the retail giant is moving…

 Raul Delapena Setiawan

 Reynand Wu

 Sagoh
4

5

6

Beyond the Transaction: How to Transform Your Email List Into a Thriving Community
Ali Ikhwan
- October 24, 2026
- 1 views
