
 Nana Muazin
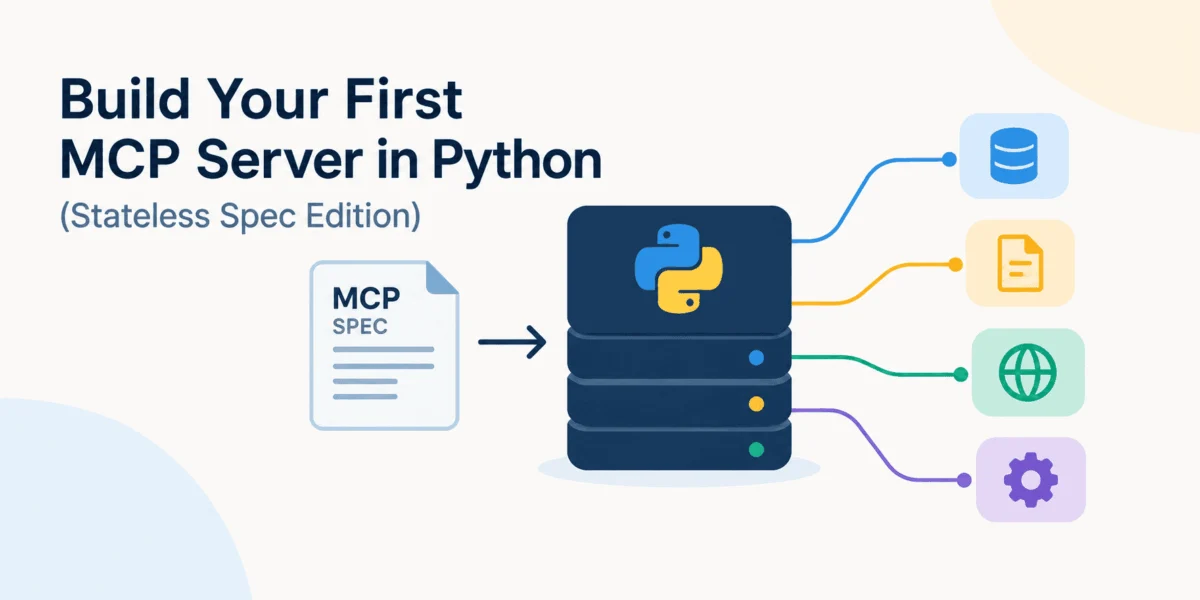
The Model Context Protocol (MCP) has undergone a fundamental architectural transformation. Following the release of the July 28, 2026, specification, the protocol has transitioned to a stateless core, fundamentally changing how developers build, deploy, and scale AI-integrated tools. For Python developers, this evolution is perfectly captured in the newly released v2 of the official Python SDK, which abstracts away the complexity of session management in favor of a clean, function-oriented API.
This shift marks a departure from the "session-heavy" paradigms that characterized early AI integration, moving the ecosystem toward a future of standard HTTP infrastructure and simplified, high-performance scalability.
The Evolution of the Model Context Protocol
The Shift to Statelessness
Historically, MCP required clients to establish a formal protocol session before data could be exchanged. This necessitated the use of Mcp-Session-Id headers to track state across multiple requests, effectively requiring "sticky" connections. In enterprise environments, this created a significant bottleneck: load balancers had to be configured to route requests to specific server instances to maintain session integrity.
The 2026-07-28 specification effectively obsoletes this requirement. By moving to a stateless model, MCP servers no longer require a pre-established handshake. Every request is now self-contained, carrying all necessary context for execution. This architectural decoupling allows MCP servers to be deployed behind standard HTTP load balancers without requiring session affinity, significantly reducing the operational overhead of scaling AI-powered infrastructure.
The Rise of the v2 Python SDK
The official Python SDK has moved to v2, introducing the MCPServer class. This API is designed to make tool creation feel like standard Python development. By leveraging type hints and decorators, the SDK automatically handles the translation between Python logic and the underlying JSON-RPC schema required by LLMs. This "convention-over-configuration" approach means that developers no longer need to write verbose JSON schemas or maintain separate manifest files for their tools.
Conceptualizing the Modern MCP Server
To understand the practical impact of these changes, we can build a developer knowledge-base server. This server acts as an interface between an LLM and a collection of technical documentation.
Core Primitives
The server exposes three distinct primitives:
- Tool (
search_kb): An action-oriented function that allows the LLM to query the knowledge base with specific parameters. - Resource (
kb://articles): A read-only data exposure that allows the LLM to access the current list of available documentation. - Prompt (
draft_support_reply): A predefined template that ensures consistency in AI-generated customer support communications.
Because the server is stateless, no session memory is required. The LLM simply sends a request, the server processes it, and the response is returned. There is no background "state" being managed on the server side, which simplifies both testing and production deployment.
Step-by-Step Implementation
Setting Up the Environment
Modern MCP development favors efficiency. Using uv, the fast Python package installer and manager, we can initialize a project in seconds.
mkdir first-mcp-server
cd first-mcp-server
uv init
uv add "mcp[cli]"
This setup installs the necessary SDK tools, including the MCP Inspector, which is essential for testing tool definitions during the development loop.
Defining the Server logic
Using the MCPServer class, we define the server identity and instructions. The instructions serve as the "system prompt" for the LLM, guiding it on how to interact with the exposed tools.
from mcp.server import MCPServer

mcp = MCPServer(
    "Developer Support KB",
    instructions="Use the knowledge-base tools to answer support questions."
)
Implementing Tools with Type Hints
The beauty of the v2 SDK is that the tool’s input schema is derived entirely from the function’s signature.
@mcp.tool()
def search_kb(query: str, limit: int = 3) -> list[dict[str, str]]:
    """Search the support knowledge base."""
    # Logic implementation...
    return matches[:limit]
By defining limit: int = 3, the SDK automatically generates a schema that marks limit as optional with a default value, saving the developer from manually mapping complex parameter types.
Implications of the New Architecture
Scalability in Production
The most significant implication of the stateless update is the ease of horizontal scaling. In the past, if a developer needed to scale a server, they had to ensure that the user’s session was persisted across instances. With the new model, one can simply use a standard uvicorn deployment with multiple worker processes:
uvicorn server:app --workers 4Because the protocol is stateless, any of these four workers can handle any incoming request. If a request hits Worker 1, and the next request hits Worker 4, the transaction will succeed without error or session loss.
The "Explicit Handle" Pattern for State
Critics of stateless models often ask: "What if my application requires state, such as a shopping cart?" The MCP maintainers provide a clear answer: Application-level state should be handled explicitly, not implicitly.
Rather than letting the protocol "remember" a user, the developer should design functions that require an ID. For instance, a create_basket() tool returns a basket_id. Subsequent tools, like add_item(), must then take that basket_id as an argument. This forces the LLM to keep track of the context, making the entire interaction more transparent and easier to debug.
Development and Debugging
The inclusion of the MCP Inspector in the CLI (uv run mcp dev server.py) transforms the development experience. Developers can inspect their tool schemas, test parameters, and verify the model’s responses in a browser-based UI without needing to spin up a full LLM client. This tight feedback loop is critical for building robust AI integrations.
Supporting Data and Technical Context
The transition to the 2026-07-28 specification is not just a cosmetic change; it is a strategic alignment with the needs of modern cloud-native architectures.
| Feature | Old Model (Stateful) | New Model (Stateless) |
|---|---|---|
| Session Management | Handled by Protocol | Handled by Application |
| Routing | Requires Sticky Sessions | Compatible with Round-Robin |
| Deployment | Complex/State-dependent | Cloud-Native/Standard |
| Tool Definition | JSON Schema Manual | Derived from Type Hints |
The v2 SDK reduces the lines of code required to create a functional server by approximately 40% compared to previous implementations, primarily because the boilerplate associated with JSON-RPC schemas and manual session tracking has been eliminated.
Official Perspective and Industry Impact
The MCP team emphasizes that this change was driven by developer feedback from large-scale enterprise deployments. By removing the protocol-level session, they have eliminated the "hidden" complexity that often led to race conditions and deployment failures.
For developers in fields like medicine, finance, and engineering—where the accuracy and reliability of AI tools are paramount—this shift is a major win. It allows for the creation of "stateless, idempotent" tools that can be audited and tested with high precision. As noted by industry experts, the ability to build tools that behave consistently regardless of the infrastructure beneath them is the cornerstone of reliable AI agent behavior.
Conclusion: The Future of MCP
The shift to a stateless protocol is a coming-of-age moment for the Model Context Protocol. It signifies that the protocol is no longer just a prototype or a niche experimental framework; it is becoming a mature industry standard ready for the demands of high-traffic production environments.
By using the v2 Python SDK, developers can now build sophisticated, network-accessible tools with little more than standard Python functions. Whether you are building a simple developer knowledge base or a complex enterprise-grade AI integration, the stateless model provides the flexibility and simplicity needed to scale.
As we look toward the future, the integration of these tools into larger frameworks like FastAPI or Starlette will continue to blur the line between traditional web services and AI agents, paving the way for a more intelligent, interoperable digital ecosystem. The barrier to entry has never been lower, and the potential for innovation has never been higher.
About the Author: Kanwal Mehreen is a machine learning engineer and technical writer dedicated to the intersection of AI and practical software engineering. A Google Generation Scholar and advocate for diversity in STEM, she bridges the gap between complex machine learning research and actionable, production-ready code.

 Dwi Wanna
 Nila Kartika Wati

 Raul Delapena Setiawan


 Muslim

 Nana Wu

