
 Pevita Pearce
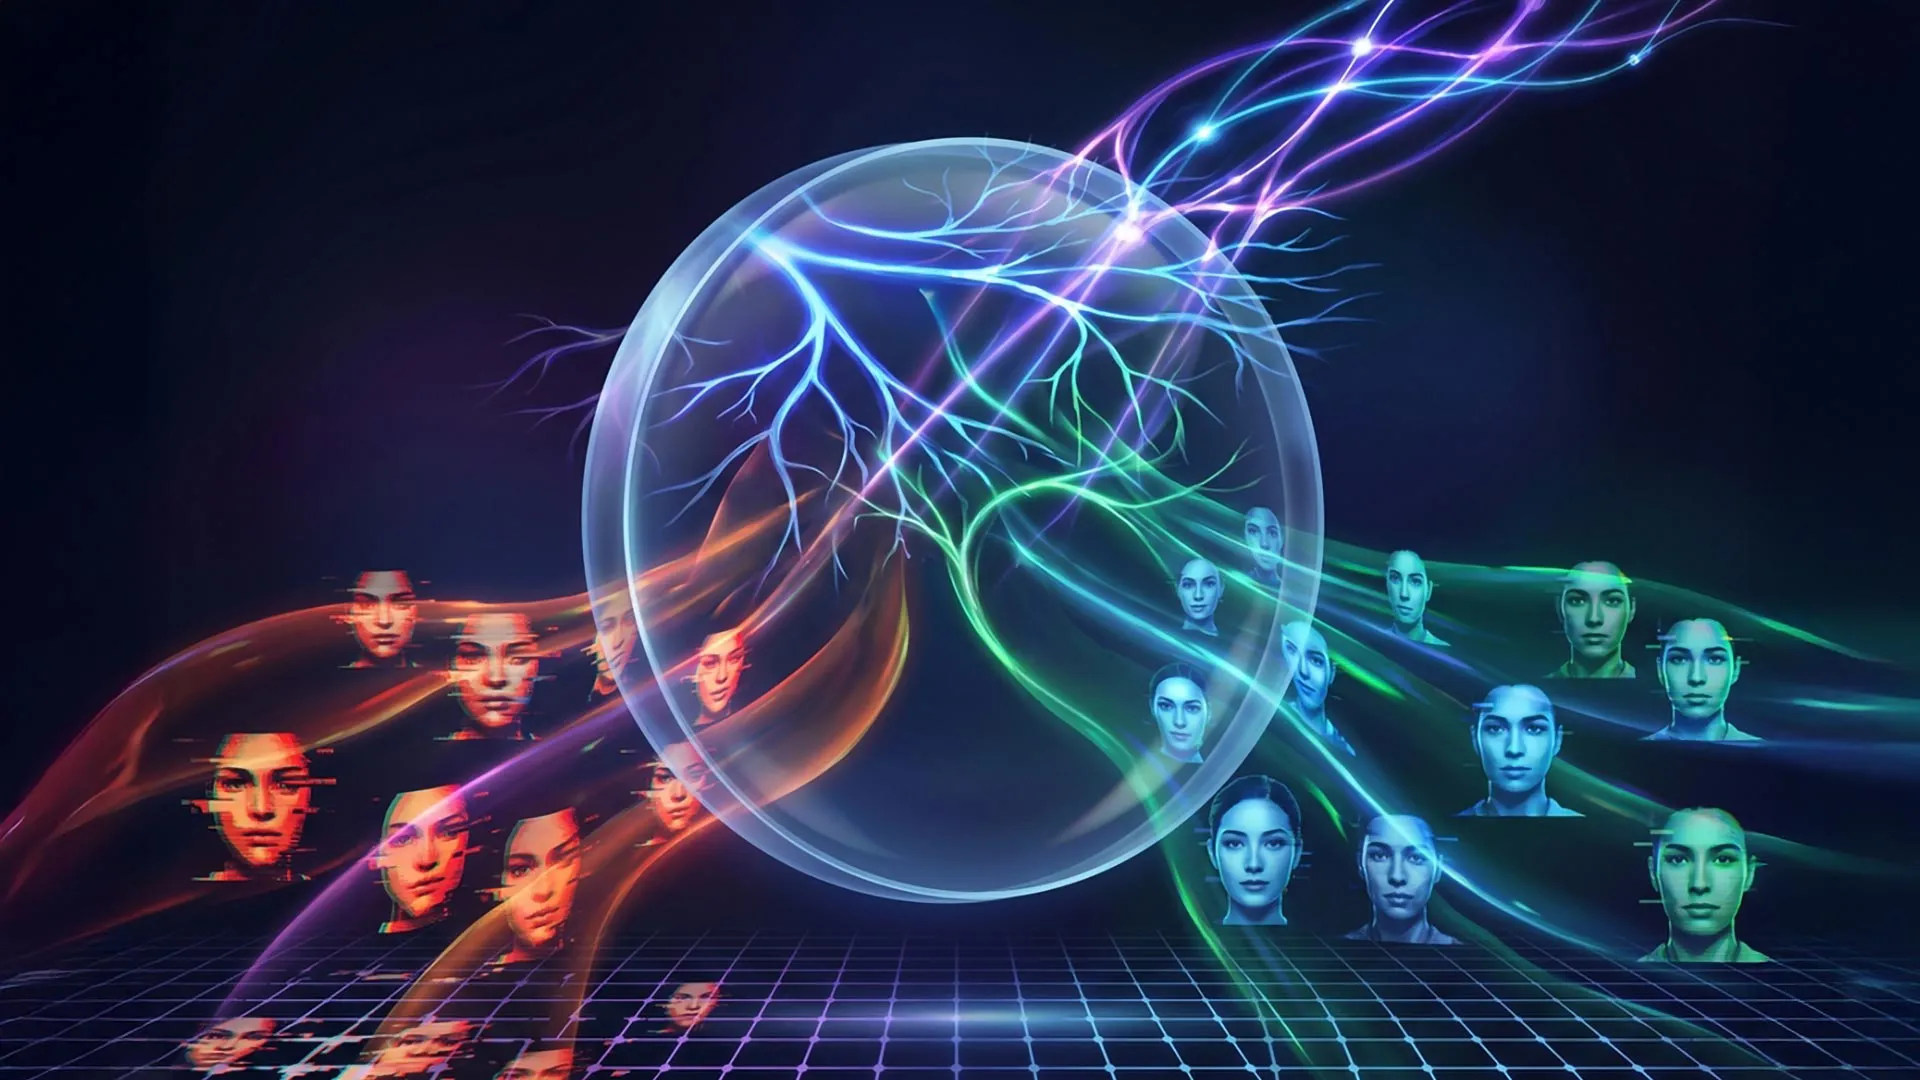
In an era where synthetic media can blur the lines between reality and fabrication, the rapid proliferation of high-fidelity deepfakes has placed an unprecedented strain on digital security infrastructure. As generative AI models become increasingly sophisticated, the task of identifying manipulated footage has transitioned from a technical challenge to a societal imperative. Now, researchers at the University of California, Los Angeles (UCLA) have unveiled a breakthrough that could fundamentally shift the paradigm of AI detection: an optical-neural processor that leverages the physics of light to identify deepfakes with unprecedented speed, efficiency, and resilience.
Led by Professor Aydogan Ozcan, the team has successfully demonstrated a hybrid digital-optical system capable of analyzing multiple video streams simultaneously. By offloading the heavy lifting of data processing to the physical propagation of light, the UCLA researchers have created a high-throughput “first line of defense” that promises to keep pace with the massive volumes of content generated daily across the internet.
The Genesis of a New Detection Paradigm
The story of this innovation begins with a fundamental bottleneck in modern computing. Traditional deepfake detectors rely on purely digital neural networks, which are computationally expensive. To analyze a video, these systems perform hundreds of billions of floating-point operations, often processing one frame after another in a sequential pipeline. As the volume of online video grows, the energy and time required to monitor this content scale linearly, leading to unsustainable costs and latency.
Furthermore, traditional systems are vulnerable to "adversarial attacks." Because their decision-making parameters are entirely digital, they are susceptible to reverse engineering. If a malicious actor can map the logic of a detector, they can subtly alter a deepfake—adding imperceptible noise or artifacts—that tricks the AI into classifying the manipulated video as authentic.
Chronology of the Research
- Initial Conceptualization: The UCLA team recognized that the limitations of digital hardware were essentially physical. They hypothesized that by integrating passive optical elements into the computational pipeline, they could replace power-hungry digital layers with physical light diffraction.
- System Design: The researchers developed a two-stage hybrid process. First, a lightweight digital encoder extracts essential spatial, spectral, and temporal features from a video. This data is converted into a phase pattern and displayed on a programmable spatial light modulator.
- Experimental Phase: The team utilized a free-space-based, passive optical decoder. They tested the architecture against the "Celeb-DF" dataset, a gold-standard benchmark for deepfake detection, successfully processing 15 videos simultaneously.
- Advanced Stress-Testing: Following initial success, the team challenged the system with newer, more complex content generated by Google’s VEO-3 model. They further refined the architecture by adding diffractive layers to improve accuracy on difficult manipulations.
Decoding the Physics: How the Optical Processor Works
The core innovation of the UCLA system lies in the use of a "passive optical decoder." Unlike digital chips that consume electricity to perform every gate operation, the optical decoder performs calculations through the diffraction of light as it passes through physical surfaces.
When the encoded phase pattern—representing the features of multiple videos—passes through these diffractive layers, the light naturally performs the matrix-vector multiplications necessary for classification. At the output, paired optical detectors measure the resulting wavefront, producing an authenticity score for each video simultaneously.
Because this process is performed in parallel during a single optical pass, the system essentially sidesteps the energy-intensive digital processing pipeline. By increasing the physical depth of the decoder—adding more optimized passive diffractive layers—the system gains the ability to identify increasingly subtle manipulations without a corresponding spike in power consumption or latency.
Supporting Data: Efficiency and Precision
The performance metrics of the UCLA processor are significant. During experiments with 15 simultaneous video streams, the system achieved an average detection accuracy of 97.79%. Perhaps most critical for a security application is the system’s sensitivity: at 99.86%, the detector successfully flagged almost every manipulated video, resulting in a false-negative rate of only 0.14%.
Even when the researchers pushed the system to its current limit, processing 18 videos in a single optical pass, the accuracy remained remarkably high at 96.13%.
Performance Against Next-Generation AI
The researchers were particularly concerned with whether the processor could keep up with the evolution of generative models. They tested the system against videos produced by Google’s VEO-3, which are designed to lack the common "telltale" artifacts found in earlier deepfakes. Even against this advanced, unfamiliar content, the system achieved 94.80% accuracy and 97.61% sensitivity after minimal fine-tuning. This suggests that the architecture is not merely a static filter, but a flexible framework capable of adapting as AI generation technology advances.
The Power of Passive Layers
One of the most compelling findings was the impact of physical hardware depth. By adding two optimized passive diffractive layers to the decoder, the team observed a 6.8% increase in accuracy when handling difficult manipulations. Because these layers are static, manufactured structures, they perform this enhanced analysis at zero additional electrical cost, offering a path to "energy-free" computational scaling that simply does not exist in the digital realm.
Resilience: Hardening the First Line of Defense
In the high-stakes world of cybersecurity, a detector is only as good as its ability to withstand tampering. The UCLA processor offers a distinct security advantage through "physical obfuscation."
In a standard digital AI, the decision-making weights are stored in accessible memory, making them easy to probe. In the UCLA processor, many of the model’s parameters are physically embedded within the structural geometry of the diffractive layers. To an attacker, these parameters are essentially "black-boxed" by the physics of the light-diffraction process. Reconstructing the detector to design an effective adversarial attack would require the attacker to possess the exact physical dimensions and material properties of the optical layers, a task far more difficult than hacking a digital software model.
Furthermore, the system demonstrated robust performance in the presence of real-world environmental degradation, including image noise, compression artifacts, and experimental misalignments. This durability suggests that the processor is ready for deployment in real-world, high-volume environments.
Implications: A Hybrid Future for Content Moderation
The research team, led by Parnian Ghapandar Kashani and Dr. Shiqi Chen alongside Professor Ozcan, emphasizes that this technology is not intended to replace existing digital detection models. Instead, it is designed to function as an intelligent "triage" system.
A Two-Tiered Approach
In a real-world application, such as a social media platform or a news-verification service, the optical processor would serve as the primary screening layer. Massive volumes of content would be channeled through the optical system at high speed and low cost.
- Tier 1 (Optical): Parallel screening of high-volume video to filter out clear fakes and flag suspicious content.
- Tier 2 (Digital): Content identified as "suspicious" by the optical processor is then sent to deep-learning digital models for a granular, resource-intensive analysis.
This hybrid approach addresses the fundamental scaling issue of the internet. By using optical processing to handle the bulk of the workload, platforms can maintain high sensitivity and security while keeping energy consumption and computational costs manageable.
Future Applications
The implications of this work extend far beyond social media moderation. As surveillance technology and government media-authentication protocols become more reliant on AI, the need for high-throughput, secure, and energy-efficient detectors will only grow. The UCLA processor could eventually be integrated into:
- Automated Content Moderation: Enabling platforms to process millions of uploads per minute with minimal latency.
- Journalistic Verification: Assisting news organizations in rapidly filtering out misinformation during breaking news events.
- National Security: Protecting public discourse from state-sponsored deepfake campaigns aimed at destabilizing political processes.
As the authors note in their study, Scalable, Energy-Efficient Optical-Neural Architecture for Multiplexed Deepfake Video Detection, published in eLight, this work represents a new frontier in "optical computing." By bridging the gap between physical optics and artificial intelligence, the UCLA team has provided a blueprint for a future where our defensive tools are as fast, adaptive, and sophisticated as the threats they are meant to counter. In the race between the creators of synthetic reality and the guardians of truth, the use of light itself may well be the decisive advantage.

 Nana Wu
 Asro

 Laily UPN

 Iffa Jayyana

 Rifan Muazin

 Suro Senen

 Lina Hope

 Lina Irawan
